Turn AI potential into trusted, measurable execution.
ReliablyWE, from ReliablyME, is being developed to connect accepted human–AI commitments with timely assistance, evidence and authorized review. Start with one consequential workflow and define what a trustworthy outcome would look like.
What happens after the AI recommendation?
See the complete illustrative journey: how people clarify commitments, resolve blocked handoffs and review AI-assisted work, then follow through from approval to confirmed receipt.
ReliablyWE is being developed. Capabilities, supported channels and readiness must be verified for each system, version and pilot.
Find the handoff problem before redesigning the workflow
When work is marked complete but still needs chasing, clarification or rework, start by understanding what happens today. Review one recurring workflow: what was agreed, where dependencies changed, who owned the next action and who accepted the result.
A scoped review could identify recurring friction, gaps in the evidence and one or two improvements worth testing. The aim is to find a useful next step, not assume you need a new platform.
For operations leaders
When recurring handoffs need chasing or completed work returns for clarification or rework, examine one workflow across the people and teams involved. Start with ownership, changed dependencies and acceptance evidence—not a presumption that a new platform is needed.
Discuss an operational workflowStart with a non-confidential example. Any deeper review would have an agreed scope and data permissions.
What do you need to prove?
ReliablyWE is our emerging product for trusted human–AI execution. It builds on ReliablyME's follow-through foundation. For each proposed pilot, we distinguish available functionality, tested prototypes and planned capabilities, and agree the evidence and human review needed before expanding scope.
AI, OD & L&D leaders
Readiness to be verified for each pilotProve AI adoption and operational change — not usage dashboards or attendance records.
Prove AI adoption & operational changeCompliance & quality operations leaders
Readiness to be verified for each pilotProve corrective-action effectiveness — that CAPA took hold in the real workflow, not just in the log.
Prove corrective-action effectivenessUsage is not the same as follow-through.
We turn these signals into a sponsor-ready proof pack so the next investment decision is based on evidence, not anecdotes.
Commitments accepted
Which person or team accepted the commitment, and under whose authority?
Support delivered
Did prompts and check-ins produce reflection and action?
Evidence recorded
Observed facts, submitted evidence, and calculated indicators — kept distinct.
Reviewed outcomes
Who reviewed the evidence, and what decision did they make?
Industry research consistently identifies a gap between AI experimentation and measurable operational value. Citations and sources are listed in Resources.

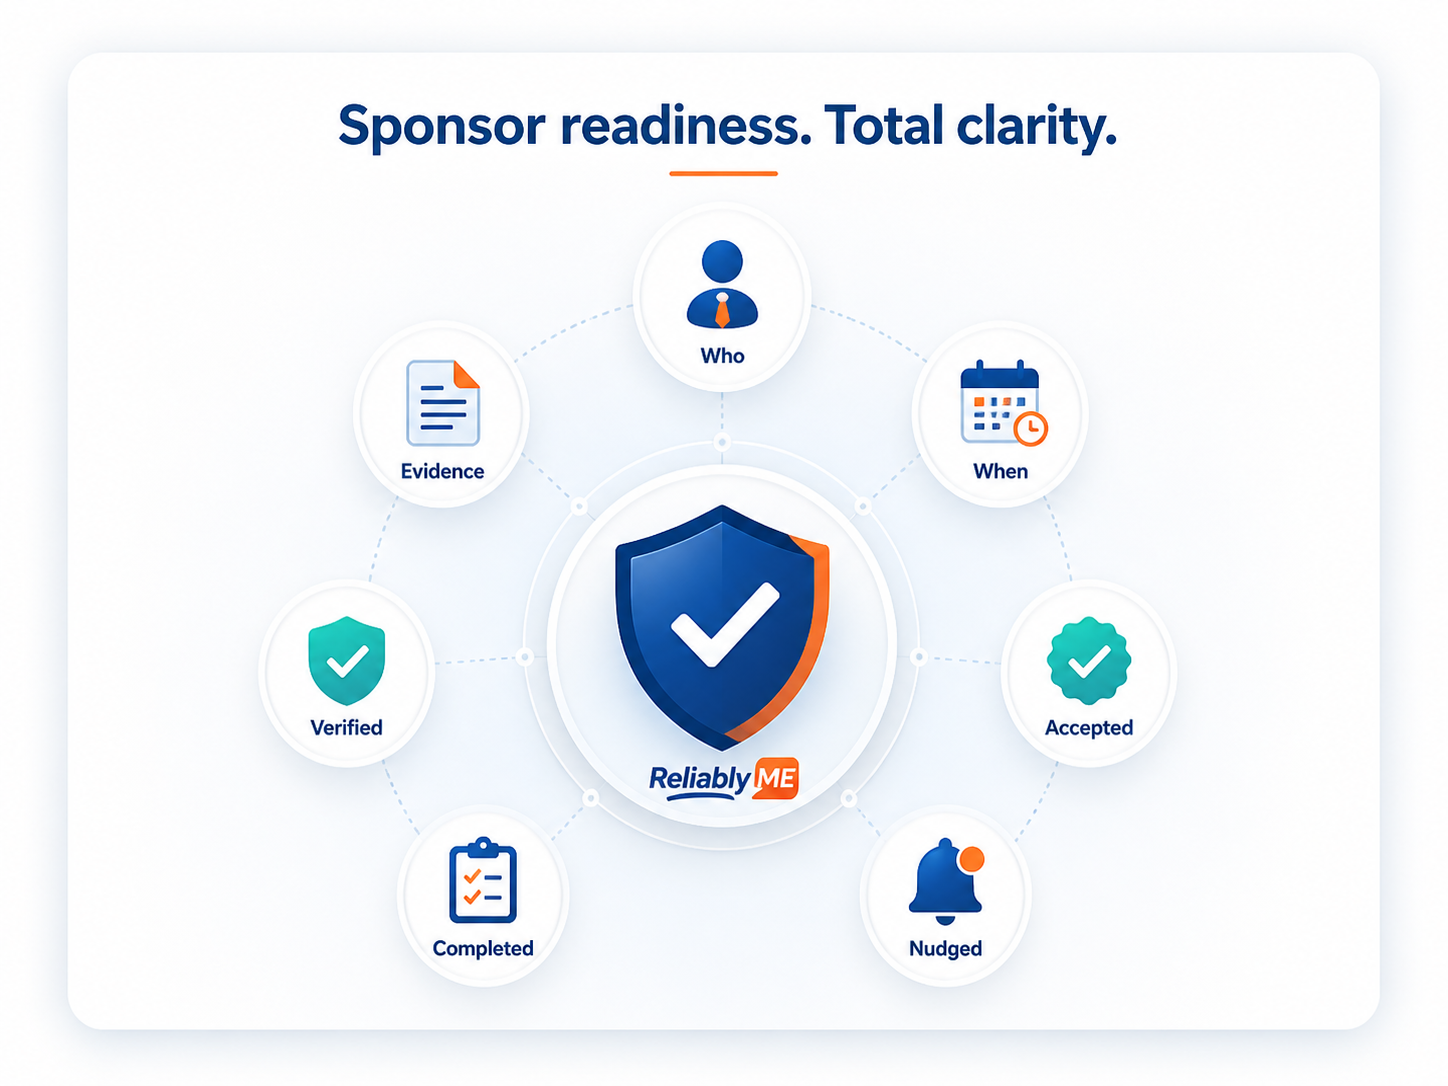
The seven questions every sponsor should be able to answer.
- Which individual or team accepted the commitment — and on whose authority?
- To whom did they commit — and by when?
- Was the authority to act legitimate, bounded, and attributable?
- Were they supported to follow through?
- Did they complete the action they committed to?
- What evidence was observed, submitted, or calculated?
- Who reviewed the outcome, and what did they decide?
Personal responsibility-first
Whose commitments — and on what terms.
ReliablyME captures commitments made by individual employees, team members, and managers to take specific actions on behalf of themselves, their team, or their organization. AI agents do not make commitments equivalent to people and hold no independent organizational authority: they may propose, analyze, remind, support, and execute only within authority delegated by authorized people or institutions via TECP — authority that is legitimate, bounded, attributable, and revocable.
- Each person's commitments are explicitly accepted, not imposed.
- Each person's commitments are descriptive, not punitive.
- Each person's commitments are alongside their teams — not surveillance.
Built on personal responsibility — requests can come from colleagues or systems; a commitment is recorded only when the responsible person explicitly accepts it. Nudges respect quiet hours, time zones, and tone. Evidence signals are descriptive coaching tools for the individual or team, never punitive or used for surveillance.
From commitment to verifiable evidence.
Illustrative animation. Channels shown are examples, not evidence of current product support; supported channels are verified for each product version and pilot.
Capture each person's commitment
Convert intent from training, workshops, and AI rollouts into structured commitments individuals and teams have personally accepted.
Support follow-through
Lightweight prompts via SMS, WhatsApp, Slack, or web reach the committed person in the flow of work.
Record the action and its evidence
Track who accepted, who acted, and what evidence was observed or submitted — not just generic activity.
Deliver proof packs for review
Sponsor-ready reports showing which individuals and teams followed through — so leaders, auditors, and consultants can review outcomes.
Embedded in the tools teams already use.
The follow-through foundation connects with channels of work; readiness and supported channels must be verified for each product version and pilot.

Flagship integration
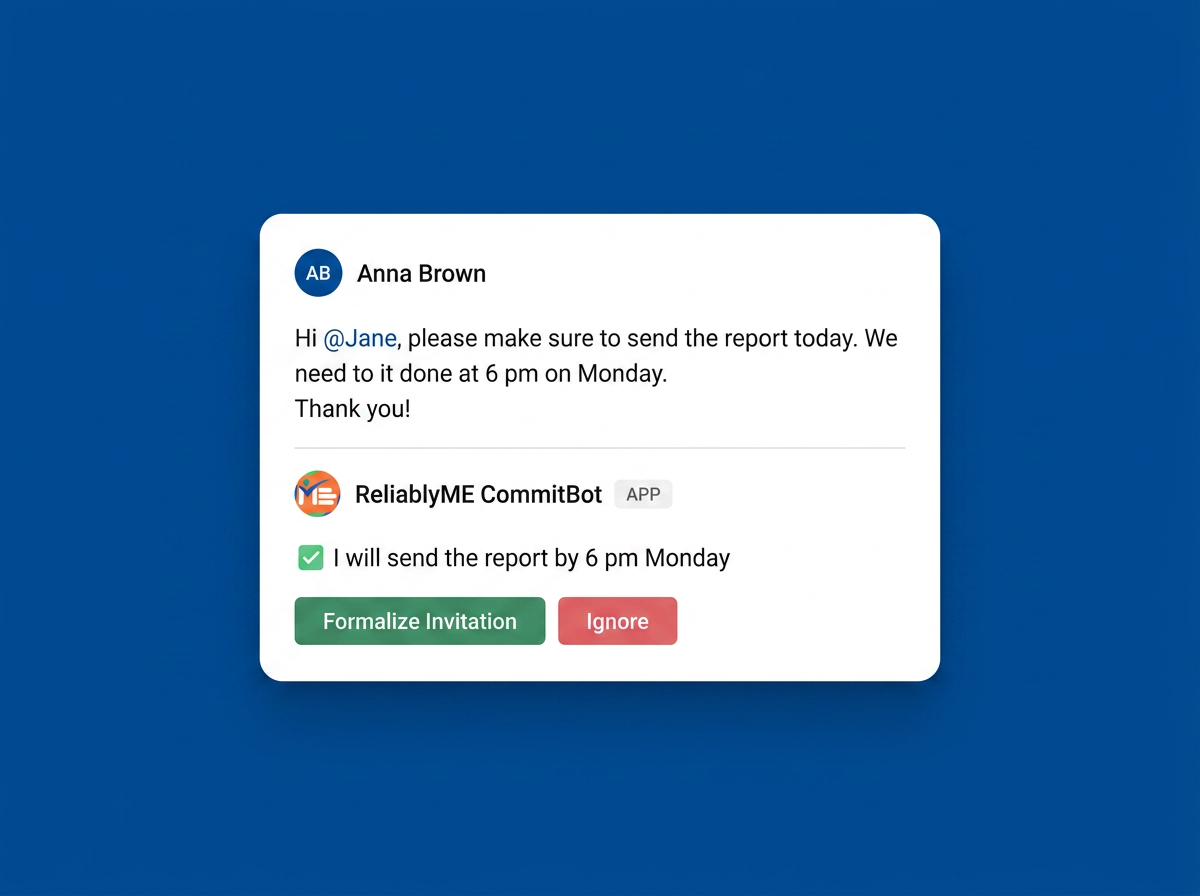
CommitBot on Slack
Powered by ReliablyME
- Commitments captured in-channel
- Nudges delivered where work happens
- Lightweight evidence trails for follow-through
- Commitment and follow-through evidence, with capabilities confirmed for each pilot.
What we assess for each system, version and pilot.
Deployment review
Hosting, security and integration requirements are reviewed for each deployment; no specific enterprise certification or deployment model is claimed here.
Channel readiness by version
Slack, SMS / WhatsApp, web, mobile and chatbot channels are considered individually; supported channels and readiness must be verified for the relevant product version and pilot.
Sensitive-workflow review
Security, privacy and workflow requirements must be assessed for each use case; this is not a claim of healthcare compliance or suitability.
Practitioner networks
Pilot opportunities may be explored through organization-development and transformation networks; no formal partnership is claimed unless separately confirmed.
What ReliablyME is not
Not a generic reminder app. Not a habit tracker. Not a task tracker. Not surveillance, and not behavior scoring.
ReliablyME Follow-Through is the authority, commitment, and evidence layer for people and teams — evidence is proportional and signals are descriptive, never punitive. AI agents hold no independent organizational authority.
Learn how leaders prove follow-through.
The follow-through evidence playbook
A practical guide for OD, L&D, and AI adoption leaders building 30–90 day journeys.
Learn more →From Training to Reviewable Evidence
Whitepaper: how to make hygiene training and corrective actions stick, with follow-through evidence prepared for human review.
Learn more →From AI usage to AI accountability
Webinar: why dashboards stall and what proof packs change for sponsors.
Learn more →Start small. Prove follow-through. Decide with evidence.
A ReliablyME pilot is designed to be low-risk and evidence-rich: one sponsor, one team or cohort, one target behavior, a short nudge cadence, and a proof pack that shows what changed.
Fast scope
2–4 weeks, 5–10 individual or team commitments to take action, one measurable behavior or workflow.
Low-friction channels
Nudges and check-ins through Slack, SMS, WhatsApp, or web — no new dashboard required.
Decision-ready proof
A sponsor-ready report: commitments accepted, nudges delivered, actions confirmed, blockers surfaced, next steps.
Founding pilot incentives. Founding-cohort participants may qualify for preferred pilot pricing, a message-pack credit, a pilot-to-plan credit, and a co-authored case-study option.
These are proposed pilot offer terms, not a guarantee of product capability or readiness. Supported capabilities, channels and acceptance evidence must be agreed for each system, version and pilot.
ReliablyWE is being developed on ReliablyME's follow-through foundation. TECP is the separate emerging architecture for policy-bounded, human-authorized AI execution. These are distinct layers; readiness must be verified for each system, version and pilot.
Explore the TECP architecture previewStart with your workflow.
Discuss one recurring workflow, the handoff problem and a useful next step.